
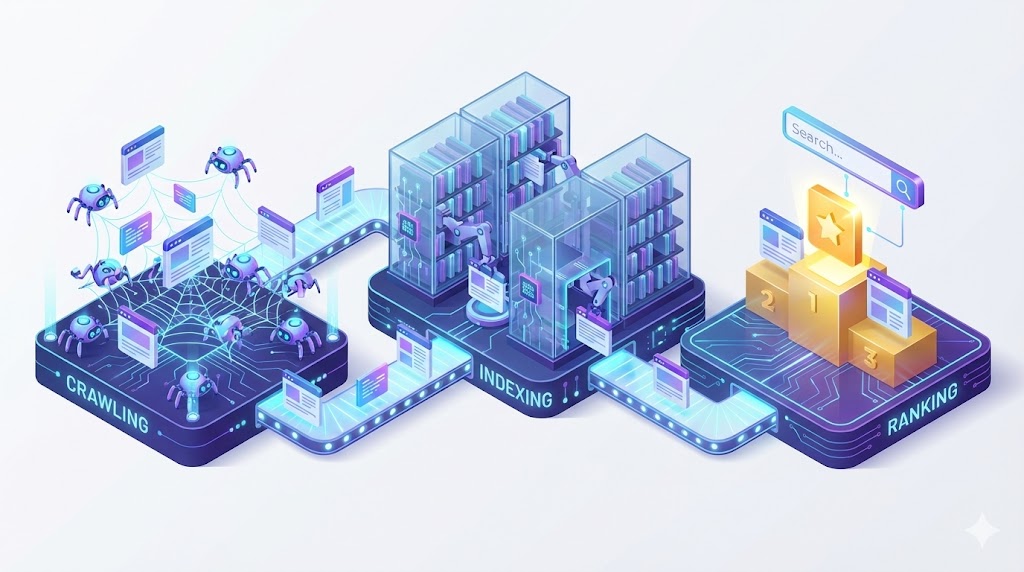
Search engines help people find useful information across billions of webpages. They do not usually search the entire live web every time someone enters a query. Instead, systems such as Google discover pages, process and store information about them, and then select relevant results when a person searches.
The process is commonly explained in three stages: crawling, indexing and serving or ranking search results. Understanding the difference helps website owners diagnose why a page is not appearing in search and decide what to improve.
How do search engines work?
Think of a search engine as a very large, constantly updated library. Crawlers discover and fetch webpages. Indexing systems analyse the content and decide whether and how it should be stored. When someone searches, ranking systems look through the available index and present results that are relevant to the query.
These stages are connected, but they are not automatic guarantees. A page can be discovered without being crawled, crawled without being indexed, or indexed without receiving prominent visibility for a particular query.
1. Crawling: discovering webpages
Crawling is the process of finding URLs and fetching their content. Search engines use automated software called crawlers, bots or spiders. Google’s main web crawler is known as Googlebot.
How do crawlers discover pages?
- Links: Crawlers follow links from pages they already know about to other URLs.
- XML sitemaps: A sitemap can provide information about important URLs on a website.
- Previously known URLs: Search engines may revisit URLs discovered earlier to check for changes.
- External references: Links from other websites can help search engines discover a page.
A sitemap is a discovery hint, not a guarantee that every listed URL will be crawled or indexed. Clear internal links remain important because they help visitors and crawlers navigate the site.
What can prevent crawling?
- A robots.txt rule blocks the crawler from accessing a URL.
- The server returns errors, times out or cannot handle requests reliably.
- The page requires a login or other access that the crawler cannot use.
- Important pages have no crawlable links pointing to them.
- Network, DNS or hosting problems prevent access.
Important: robots.txt controls crawling, not indexing by itself. A URL blocked from crawling may still be known to a search engine through links. If you need to prevent a page from appearing in Google Search, use the appropriate indexing controls, such as a crawlable noindex directive, rather than relying on robots.txt alone.
2. Indexing: understanding and storing content
After a page is fetched, search engines analyse its content and other information to understand what it is about. This process is called indexing. Systems can process visible text, headings, title elements, images, video, links, language information and technical directives.
What happens during indexing?
- The page content and important resources are processed.
- The topic, language and other page information are analysed.
- Similar or duplicate URLs may be grouped together.
- A representative or canonical URL may be selected for a group of similar pages.
- The page may be stored in the search index if it meets the search engine’s requirements.
Indexing is not guaranteed. A page can be crawled and still not be selected for indexing. A canonical tag is a signal that helps indicate a preferred URL; it is not an absolute command that guarantees the selected canonical.
Common reasons a page may not be indexed
- A
noindexdirective tells search engines not to index the page. - The page is a duplicate or very similar to another URL.
- The page contains little unique value for users.
- Important content cannot be accessed or rendered properly.
- The page is not yet discovered or processed.
- Technical problems prevent search engines from understanding the page.
Use the URL Inspection tool in Google Search Console to check Google’s reported indexing status and inspect the page. Remember that a successful crawl does not mean indexing is guaranteed.
3. Ranking and serving search results
When someone searches, the search engine looks for content that may satisfy the query and orders the results using many automated systems and signals. The results can differ depending on the query and context, including language, location and device.
Search systems aim to show relevant and useful information. Factors can include the meaning of the query, relevance of the page, quality and usefulness of content, usability, freshness when appropriate, and signals about the page and website. No single checklist or metric guarantees a ranking.
What can influence search visibility?
- Relevance: Does the page answer the question or meet the need behind the search?
- Helpful content: Does it provide accurate, clear and useful information?
- Page experience: Can people access and use the page across devices?
- Context: Does the result fit the language, location and other aspects of the search?
- Search features: The results page may include maps, images, videos, product results or other features depending on the query.
Being indexed does not mean a page will rank highly. Search engines choose results for each query, and visibility can change as content, competitors and user needs change.
Crawling vs indexing vs ranking: key differences
| Stage | Main purpose | Useful checks | Possible issue |
|---|---|---|---|
| Crawling | Discover and fetch a URL | URL Inspection, robots.txt, server logs, internal links | Blocked URL or server error |
| Indexing | Understand and store page information | URL Inspection, canonical, noindex, rendered content | Duplicate, noindex or content not selected |
| Serving / ranking | Select and order results for a query | Search Console queries, page relevance and content review | Page does not match intent or is less competitive |
Practical example: how a new blog post appears in search
- You publish a new article on your website.
- A crawler discovers its URL through an internal link or sitemap.
- The crawler fetches the page and may render its content and resources.
- Indexing systems analyse the page, its content and canonical information.
- If the page is selected for indexing, it can become eligible to appear in relevant search results.
- When someone searches for a related topic, ranking systems decide whether and where the page is shown.
This process can take time. There is no guaranteed schedule for crawling, indexing or ranking, and submitting a URL does not guarantee inclusion.
How to help search engines discover and understand your website
Make important pages easy to reach
Use logical navigation and relevant internal links. Important pages should not be isolated from the rest of the website. Use standard crawlable links with descriptive anchor text.
Maintain a useful XML sitemap
Include the canonical URLs you want search engines to discover. Keep sitemap entries accurate and update modification dates when page content meaningfully changes. A sitemap supports discovery but does not force indexing.
Check robots.txt and indexing directives
Review robots.txt to ensure important resources and pages are not accidentally blocked. Check page-level robots directives and HTTP headers for unwanted noindex instructions.
Use clear page content and structure
Write descriptive titles, clear headings and useful main content. Make sure important information is available as text and that images have appropriate alternative text. Avoid creating multiple URLs with substantially duplicated content when one useful page would serve the user better.
Keep your website reliable
Fix server errors, broken internal links and redirect loops. Make sure important pages work on mobile devices and that the main content can be accessed without unnecessary barriers.
How to troubleshoot a page that is missing from Google
- Open Google Search Console and select the correct website property.
- Use URL Inspection to check the exact page URL.
- Review whether Google has discovered and crawled the URL.
- Check the indexing status, selected canonical and any reported reasons for exclusion.
- Test the live URL and confirm it returns the expected HTTP status.
- Review robots.txt, meta robots directives and canonical tags.
- Check internal links and sitemap inclusion.
- Improve the page if it is outdated, unclear, duplicated or not useful enough.
- After fixing a real issue, request indexing where appropriate and monitor the result.
Do not repeatedly request indexing without making a meaningful change. Search Console is a diagnostic tool, not a way to force Google to index a URL.
Common SEO misconceptions
- “Crawled means indexed.” Not true. A crawled page may not be selected for indexing.
- “Indexed means it will rank first.” Indexing only makes a page eligible to appear; ranking depends on the query and many other factors.
- “A sitemap guarantees indexing.” A sitemap helps search engines discover URLs but does not guarantee crawling or indexing.
- “robots.txt removes a page from Google.” It controls crawling. Use the correct indexing directive when you need to prevent indexing.
- “Paying Google guarantees better organic rankings.” Google does not accept payment to crawl a site more frequently or to rank organic pages higher.
FAQs
What are the three main stages of Google Search?
The main stages are crawling, indexing and serving search results. Crawling discovers and fetches pages, indexing analyses and stores information, and serving selects results for a user’s query.
Can a page be crawled but not indexed?
Yes. Crawling and indexing are separate processes. A page may be fetched but not selected for the search index.
How long does Google take to index a new page?
There is no fixed timeline. It depends on discovery, crawling, processing and other factors. Google does not guarantee that a page will be indexed.
Does submitting a sitemap improve rankings?
A sitemap can help search engines discover URLs, but it does not directly guarantee higher rankings or indexing.
What is the difference between crawling and indexing?
Crawling is fetching a page. Indexing is analysing and potentially storing information about that page so it can be considered for search results.
How can I check whether a page is indexed?
Use the URL Inspection tool in Google Search Console. It provides Google’s reported indexing information for the URL and can help identify issues.
Official resources
- Google Search Central: In-depth guide to how Google Search works
- Google Search Central: SEO Starter Guide
- Google Search Central: Introduction to robots.txt
- Google Search Console: URL Inspection tool
Key takeaway: Crawling, indexing and ranking are different stages. Make your important pages accessible, easy to understand and genuinely useful, then use Search Console to diagnose issues. No technical setting or SEO change can guarantee that a page will be indexed or rank in a particular position.